<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://dnietolugilde.com/feed.xml" rel="self" type="application/atom+xml" /><link href="https://dnietolugilde.com/" rel="alternate" type="text/html" /><updated>2026-10-07T16:06:01+00:00</updated><id>https://dnietolugilde.com/feed.xml</id><title type="html">Diego Nieto Lugilde</title><subtitle></subtitle><author><name>Diego Nieto Lugilde</name></author><entry><title type="html">Setting a PostgreSQL server for the European Pollen Database (EPD)</title><link href="https://dnietolugilde.com/setting-a-postgresql-server-for-the-european-pollen-database-epd/" rel="alternate" type="text/html" title="Setting a PostgreSQL server for the European Pollen Database (EPD)" /><published>2016-11-04T16:52:00+00:00</published><updated>2016-11-04T16:52:00+00:00</updated><id>https://dnietolugilde.com/setting-a-postgresql-server-for-the-european-pollen-database-epd</id><content type="html" xml:base="https://dnietolugilde.com/setting-a-postgresql-server-for-the-european-pollen-database-epd/"><![CDATA[<p>In this vignette we will explain and illustrate how to install a PostgreSQL server in Windows and Ubuntu, and how to mirror the European Pollen Database (EPD) into the server. The general procedure include the next steps:</p>
<ol>
	<li>Download and install PostgreSQL server</li>
	<li>Download EPD data for PostgreSQL</li>
	<li>Setup PostgreSQL for EPD:
<ul>
	<li>Create mandatory users for EPD</li>
	<li>Create a database for EPD into the server</li>
</ul>
</li>
	<li>Dump EPD data into the new database</li>
</ol>
<!-- # Download and install PostgreSQL server {.tabset} -->
<h1>Download and install PostgreSQL server</h1>
<p>The first step is to download and install the PostgreSQL server. This step changes depending on your operating system (OS). Select your OS in the tabs below.</p>
<h2>Windows</h2>
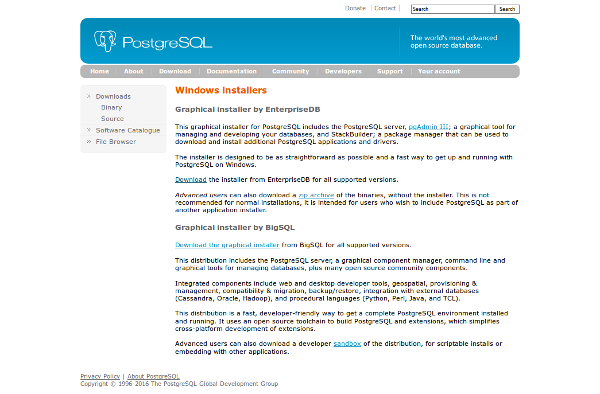
<p>You can download Windows binary files of PostgreSQL server latest version, which include the graphical interface pgAdminIII, from <a href="https://www.postgresql.org/download/windows/">https://www.postgresql.org/download/windows/</a>. Currently (2016/06/13), there are two providers: EnterpriseDB and BigSQL. BigSQL provides a much richer installation of the server with a lot of complements that are intended for developers and that will be useless for a low profile user. Hence, I recommend to use binary files from EnterpriseDB. The file name should looks like <code>postgresql-XXXX-windows-YYY.exe</code> (Xs indicate the version number and Ys the computer architecture: x86 or x64).</p>

<p>[caption id=”attachment_536” align=”alignnone” width=”600”]<img class="alignnone size-full wp-image-536" src="https://dnietolugilde.files.wordpress.com/2018/07/postgresql-website.png" alt="PostgreSQL-website" width="600" height="394" /> Download PostgreSQL website.[/caption]</p>
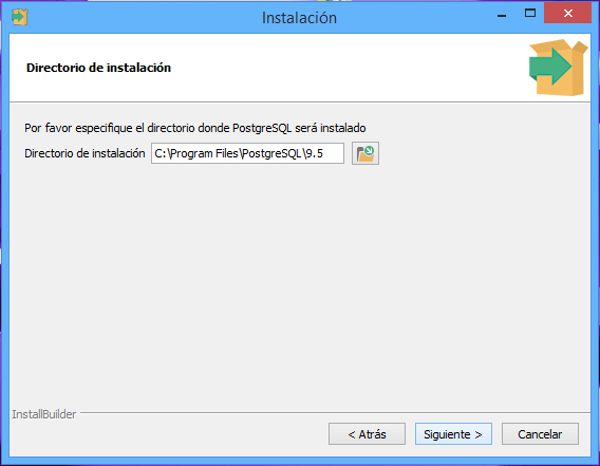
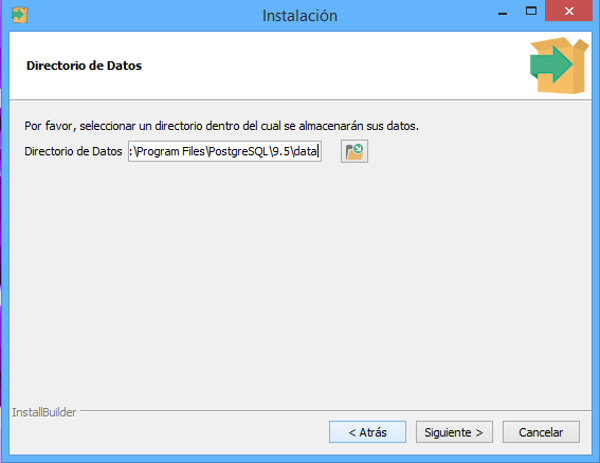
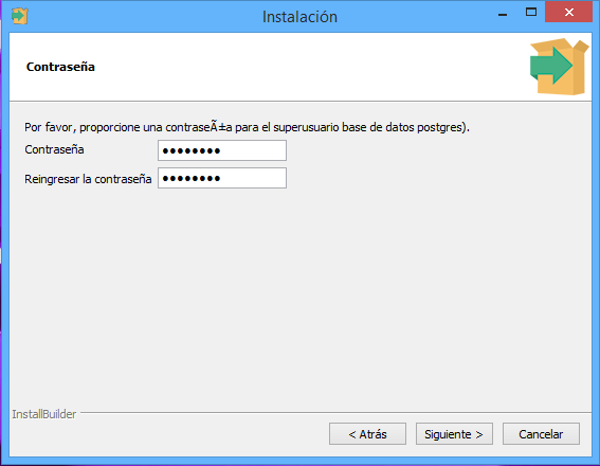
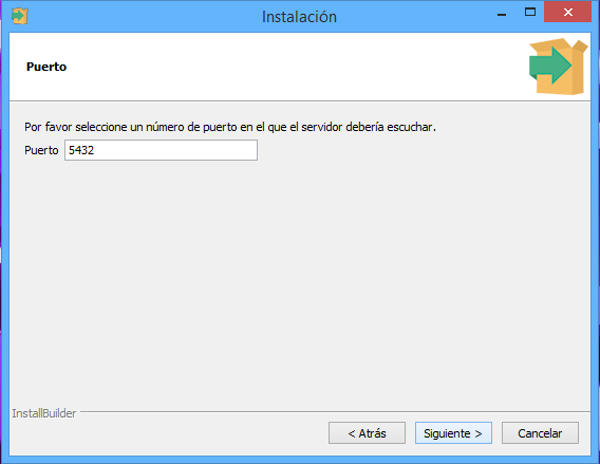
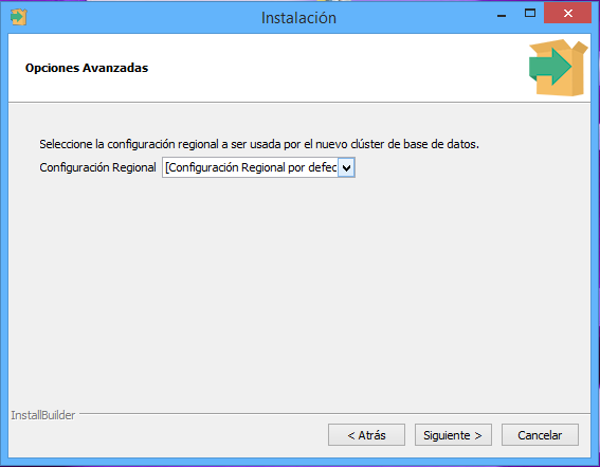
<p>Installation wizard starts with a double click on the binary file (as any other Windows program). Then, it allows you to change the values for different configuration parameters: installation directory, data directory, or the communication port. You can change those or use the default values. It is important to remember those values (specially if you change them). Next, the installation wizard ask you for a password (has to be filled twice). This password is for a special user of the database called “postgres”. This user is the default superuser or administrator of the database server. User “postgres” can create new users, databases, etc. It is important to provide a password for security reasons and to remember it, otherwise you won’t be able to make any operation with the server.</p>

<p>[caption id=”attachment_542” align=”alignnone” width=”600”]<img class="alignnone size-full wp-image-542" src="https://dnietolugilde.files.wordpress.com/2018/07/3.png" alt="3" width="600" height="466" /> Installation windows to specify PostgreSQL installation folder.[/caption]</p>
<p>[caption id=”attachment_543” align=”alignnone” width=”600”]<img class="alignnone size-full wp-image-543" src="https://dnietolugilde.files.wordpress.com/2018/07/4.png" alt="4" width="600" height="463" /> Installation windows to specify PostgreSQL data folder.[/caption]</p>
<p>[caption id=”attachment_545” align=”alignnone” width=”600”]<img class="alignnone size-full wp-image-545" src="https://dnietolugilde.files.wordpress.com/2018/07/6.png" alt="6" width="600" height="466" /> Installation windows to specify the password for postgres user.[/caption]</p>
<p>[caption id=”attachment_546” align=”alignnone” width=”600”]<img class="alignnone size-full wp-image-546" src="https://dnietolugilde.files.wordpress.com/2018/07/7.png" alt="7" width="600" height="464" /> Installation windows to specify communication port number.[/caption]</p>
<p>[caption id=”attachment_547” align=”alignnone” width=”600”]<img class="alignnone size-full wp-image-547" src="https://dnietolugilde.files.wordpress.com/2018/07/8.png" alt="8" width="600" height="467" /> Installation windows to specify regional configuration for the server.[/caption]</p>
<p>When the installation wizard is over, you have to modify the setup in Windows path to include the <code>bin</code> folder in the installation directory of PostgreSQL. This allows you to run PostgreSQL commands in the command line from any folder in your computer. To do so, you need to right click on <code>System</code>, then sequentially click on <code>Properties</code>, <code>Advanced Setup</code>, <code>Env. Variables</code>, <code>System Variables</code>, and <code>Edit</code>. Then, at the end of the text box you have to include the address of the installation directory you especified during the installation wizard plus <code>\bin</code>. If you used the default values it should be something like this:</p>

<p>[sourcecode]; C:\Program Files\PostgreSQL\X.X\bin
[/sourcecode]</p>

<p>Note that the directory address has to be separated by semicolumn (;) from the rest of directories in your system path. Note also that X.X has to be changed to match the version of PostgreSQL you installed.</p>
<h2>Ubuntu</h2>
<p>Ubuntu, and most Linux distributions, include PostgreSQL server in their package repositories. Hence, installing PostgreSQL server is straightforward with the default package manager of the distribution. In Ubuntu, you can use Synaptic to search for the <code>postgresql</code> package and the <code>pgAdminIII</code> package. Installing these two packages should install the server and all necessary dependencies, and setup the required configuration. Here, the installation will create a superuser (or administrator) account called “postgres” in the server and will ask you to specify a password for this user. It is important to provide a password for security reasons and remember it, otherwise you won’t be able to make any operation with the server.</p>
<h1>Download EPD data for PostgreSQL</h1>
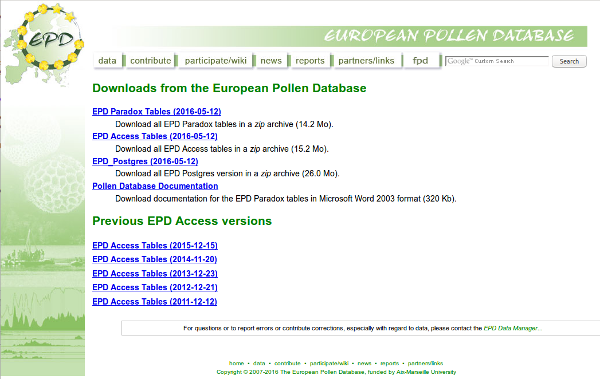
<p>Now you have to download the lastest version of the EPD for Postgres from <a href="http://www.europeanpollendatabase.net/data/downloads/">http://www.europeanpollendatabase.net/data/downloads/</a>. Save the file <code>epd-postgres-distribution.zip</code> in a specific folder of your choice and unzip the file. Now you should have four files <code>dumpall_epd_db.sql.gz</code>, <code>dump_epd_db_schema_only.sql</code>, <code>dumps_epd_all_tables.zip</code>, and <code>README</code>. The file <code>dumpall_epd_db.sql.gz</code> is also compressed and has to be uncompressed to obtain the file <code>dumpall_epd_db.sql</code>.</p>

<p>[caption id=”attachment_538” align=”alignnone” width=”600”]<img class="alignnone size-full wp-image-538" src="https://dnietolugilde.files.wordpress.com/2018/07/epdwebsite2.png" alt="EPDwebsite2" width="600" height="379" /> EPD website for downloads[/caption]</p>
<h1>Setup PostgreSQL for EPD:</h1>
<p>Before we can dump the EPD data into the server, you need to perform two basic configuration steps:</p>
<ol>
	<li>Create two specific users in the PostgreSQL server</li>
	<li>Create an empty database in the server</li>
</ol>
<p>These two steps can be done from the command line or from the graphical user interface pgAdminIII.</p>
<h2>Command line</h2>
<p>Once you are in the command line, use command <code>cd</code> to change to the same directory you unzipped the database files.</p>

<p>[sourcecode]diego@server:~$ cd epd-postgres-distribution
[/sourcecode]</p>

<p>Then, use the <code>psql</code> command to start working with the PostgreSQL server, which will change the prompt to let you know you are in a PostgreSQL prompt. Specifically, you specify that want to connect to the server with the superuser <code>-U postgres</code> and the address of the server (<code>-h localhost</code>).</p>

<p>[sourcecode]diego@server:~/epd-postgres-distribution$ psql -U postgres -h localhost
Password for user postgres:
psql (9.5.3)
SSL connection (protocol: TLSv1.2, cipher: ECDHE-RSA-AES256-GCM-SHA384, bits: 256, compression:off)
Type “help” for help.</p>

<p>postgres=#
[/sourcecode]</p>

<h3>Create mandatory users for EPD</h3>
<p>First, you should create two specific users in your local PostgreSQL server: <code>wwwadm</code> and <code>epd</code>. These two users are defined in the original EPD database server and are required to properly dump the data into the database in your local server. Users in PostgreSQL are also know as roles. To create a new role for the server we use the <code>CREATE ROLE</code> command, with the argument <code>WITH PASSWORD</code> to specify the desired password for each user. You can use any password of your choice, but do not forget these passwords.</p>

<p>[sourcecode]postgres=# CREATE USER wwwadm WITH PASSWORD ‘wwwadm_password’;
CREATE ROLE
postgres=# CREATE USER epd WITH PASSWORD ‘epd_password’;
CREATE ROLE
[/sourcecode]</p>

<h3>Create a database for EPD into the server</h3>
<p>Now, you can create a database for the EPD with the <code>CREATE DATABASE</code> command. In the example, we created a database called <code>epd</code> but you can select a different name if you want. Note that commands in postgresql prompt end with semicolom <code>;</code>.</p>

<p>[sourcecode]postgres=# CREATE DATABASE epd;
CREATE DATABASE
[/sourcecode]</p>

<h2>pgAdminIII</h2>
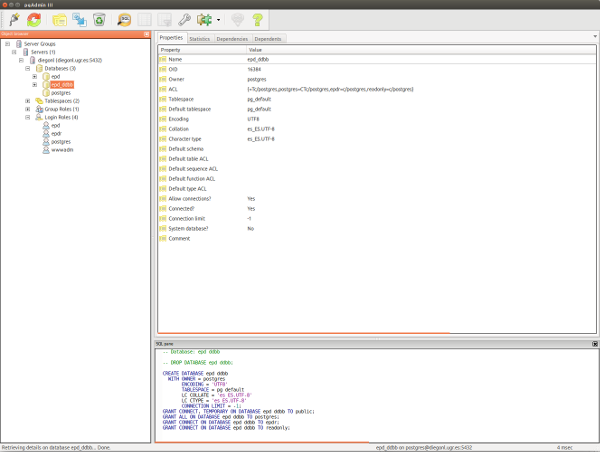
<p>pgAdminIII is a graphical user interface to manage PostgreSQL servers. It eases basic operations with PostgreSQL databases for no-advanced users that are used to work with the command line. It is also usefull to visually inspect tables in the database. If you want to give it a try or use it instead of the command line, you should look for pgAdminIII in your system and run it.</p>

<p>The program interface have three different parts: a side bar pannel in the left (<code>Object browser</code>) with the structure of the server and all its elements (databases, users, etc) and two pannels at the right. The right upper pannel provides details (<code>Properties</code>, <code>Statistics</code>, <code>Dependencies</code>, and <code>Dependents</code>) for the element that is selected in the left pannel and the right bottom pannel (<code>SQL pane</code>) shows text details of the selected element in SQL language.</p>

<p>[caption id=”attachment_539” align=”alignnone” width=”600”]<img class="alignnone size-full wp-image-539" src="https://dnietolugilde.files.wordpress.com/2018/07/pgadminiii.png" alt="pgAdminIII" width="600" height="452" /> PGAdmin III[/caption]</p>
<h3>Create mandatory users for EPD</h3>
<p>To create new users (or roles) you have to right click on <code>Login Roles</code> element in the <code>Object browser</code> pannel and, then, left click on <code>New Login Role...</code>. A new window popup. In the first tab of the window (<code>Properties</code>) you have to provide a <code>Role name</code>, which is just the name for the new user. Here, you have to write <code>epd</code>. In the next tab (<code>Definition</code>) you have to provide twice the password for the new user. You can use any password of your choice. Do not change any other option in this window and click <code>Ok</code>.</p>

<p>Repeat the same proccess to create a new role called <code>wwwadm</code>.</p>
<h3>Create a database for EPD into the server</h3>
<p>To create a new database you have to right click in <code>Databases</code> element in the <code>Object browser</code> pannel and, then, left click on <code>New Database...</code>. A new window popup. In the first tab of the window (<code>Properties</code>) you have to provide a <code>Name</code> for the database. You can use any name of you choice, but it is a good practice to provide an informative name (e.g., <code>epd</code>). Do not change any other option and click <code>Ok</code>.</p>
<h1>Dump EPD data into the new database</h1>
<p>Dumping EPD data into the DDBB server requires to use the command line, and cannot be accomplished in pgAdminIII. To do so, once you are in the command line, use the <code>cd</code> command to move into the same folder you downloaded and uncompressed the EPD database for PostgreSQL. Then, you use the <code>psql</code> command to connect to the <code>epd</code> database in the PostgreSQL server as the <code>postgres</code> user. In the same line of code you use the <code>&lt;</code> symbol to parse all the <code>dumpall_epd_db.sql</code> script for PostgreSQL into the database you just created (<code>epd</code>).</p>

<p>[sourcecode]diego@server:~$ cd epd-postgres-distribution
diego@server:~/epd-postgres-distribution$ psql -U postgres -h localhost -d epd &lt; dumpall_epd_db.sql
.
.
.
REVOKE
REVOKE
GRANT
GRANT
REVOKE
REVOKE
GRANT
GRANT
REVOKE
REVOKE
GRANT
GRANT
REVOKE
REVOKE
GRANT
GRANT
REVOKE
REVOKE
GRANT
GRANT
diego@server:~/epd-postgres-distribution$
[/sourcecode]</p>

<p>Now, you can use the database from the pgAdminIII software or using the EPDr package for R.</p>]]></content><author><name>dnietolugilde</name></author><category term="Botanica y Ecologia" /><category term="Datos" /><category term="EPD" /><category term="Scripts" /><summary type="html"><![CDATA[In this vignette we will explain and illustrate how to install a PostgreSQL server in Windows and Ubuntu, and how to mirror the European Pollen Database (EPD) into the server. The general procedure include the next steps: Download and install PostgreSQL server Download EPD data for PostgreSQL Setup PostgreSQL for EPD: Create mandatory users for EPD Create a database for EPD into the server Dump EPD data into the new database Download and install PostgreSQL server The first step is to download and install the PostgreSQL server. This step changes depending on your operating system (OS). Select your OS in the tabs below. Windows You can download Windows binary files of PostgreSQL server latest version, which include the graphical interface pgAdminIII, from https://www.postgresql.org/download/windows/. Currently (2016/06/13), there are two providers: EnterpriseDB and BigSQL. BigSQL provides a much richer installation of the server with a lot of complements that are intended for developers and that will be useless for a low profile user. Hence, I recommend to use binary files from EnterpriseDB. The file name should looks like postgresql-XXXX-windows-YYY.exe (Xs indicate the version number and Ys the computer architecture: x86 or x64).]]></summary></entry><entry><title type="html">Índice de aridez</title><link href="https://dnietolugilde.com/indice-de-aridez/" rel="alternate" type="text/html" title="Índice de aridez" /><published>2013-02-05T21:54:00+00:00</published><updated>2013-02-05T21:54:00+00:00</updated><id>https://dnietolugilde.com/indice-de-aridez</id><content type="html" xml:base="https://dnietolugilde.com/indice-de-aridez/"><![CDATA[<p>Llevo unos días preparando en GRASS una nueva variable bioclimática. Se trata de un índice de aridez, calculado en base a las precipitaciones y a la ETP (Thornwaite). En este script, hay un paso que me ha resultado interesante y es una ecuación para estimar la longitud del día en función del día del año y de la latitud. Dejo aquí el script completo por si a alguien le interesa. También dejo un fichero de clasificación que hace falta para un paso intermedio del script.</p>

<p>Descarga directa: <a title="Script para calcular índice de aridez" href="http://wdb.ugr.es/~dinilu/scripts/AridityIndex.sh" target="_blank">AridityIndex.sh</a></p>

<p>Fichero de reclasificación: <a title="Fichero de clasificación usado en el script" href="http://wdb.ugr.es/~dinilu/scripts/ClassificationRules.txt" target="_blank">ClassificationRules.txt</a></p>

<p><a title="Fichero de clasificación usado en el script" href="http://wdb.ugr.es/~dinilu/scripts/ClassificationRules.txt" target="_blank"><!--more--></a></p>
<pre>#!/bin/bash

################################
# Cálculo de índice de aridez

# IA = ETPthonwaite / Panual (mensual o anual)

# ETP thornwaite = e · L (mensuales)

# e = 16⋅(10⋅tm/I)^a (mensuales)

# tm = temperature media mensual (mensuales)

# I = Σi ; i= (tm/5)^1,514 (I anual; i mensuales)

# a = 0,000000675⋅I^3 - 0,0000771⋅I^2 + 0,01792⋅I + 0,49239 (anual)

# L = Nd/30 ⋅ Nh/12 (mensuales) ; Nd = número de días del mes ; Nh = Número de horas de luz 

####################
# Script:

# Especificamos el nombre de las variables de temperatura media mensual y Precipitación Anual
tm=tasmed_6k_CCSM.
Panual=bio12_6k_CCSM_30s

# Calculamos el parámetro "i" para cada mes a partir de los datos de temp media mensual
for j in $(seq 1 12)
do 
    r.mapcalculator amap=${tm}${j} 'formula=if(A,((A/10)/5)^1.514,0,0)' outfile=i_${j} --overwrite help=-
done

# Obtenemos el parámetro "I" como la suma de los "i" mensuales
r.series input="g.mlist pattern=i_* sep=," output=I method=sum --overwrite

# Borramos los mapas mensuales "i"
g.mremove -f rast=i_* 

# Calculamos el parámetro "a"
r.mapcalculator amap=I 'formula=(0.000000675*(A^3))-(0.000077*(A^2))+(0.01792*(A))+0.49239' outfile=a --overwrite help=-

# Calculamos un valor parcial (e1) de "e"
for j in $(seq 1 12)
do 
    r.mapcalculator amap=${tm}${j} bmap=I cmap=a 'formula=16*(((10*(A/10))/B)^C)' outfile=e1_${j} --overwrite help=-
done

# Borramos los mapas de "a" y "I"
g.mremove -f rast=a,I

# Calculamos un valor parcial (e2) de "e" que depende de la longitud del mes (número de días)
for j in $(seq 1 12)
do 
    r.reclass input=${tm}${j} output=e2_${j} rules=/media/diego/LaCie/Cartografia/Scripts/GRASS/Topillo_Paleoclim_Paleobioclim_WC-PMIP2/28-ClassificationRules.txt --overwrite

    if [[ ${j} == 1 || ${j} == 3 || ${j} == 5 || ${j} == 7 || ${j} == 8 || ${j} == 10 || ${j} == 12 ]];
        then
        r.mapcalculator amap=e2_${j} 'formula=(A/10)*31' outfile=e2_${j} --overwrite help=-
    fi
    if [[ ${j} == 4 || ${j} == 6 || ${j} == 9 || ${j} == 11 ]];
        then
        r.mapcalculator amap=e2_${j} 'formula=(A/10)*30' outfile=e2_${j} --overwrite help=-
    fi
    if [[ ${j} == 2 ]];
        then
        r.mapcalculator amap=e2_${j} 'formula=(A/10)*28' outfile=e2_${j} --overwrite help=-
    fi
done

# Calculamos "e"
for j in $(seq 1 12)
do 
    r.mapcalculator amap=${tm}${j} 'formula=A-265' outfile=${tm}_tmp_${j} --overwrite help=-
    r.mapcalculator amap=${tm}_tmp_${j} bmap=e1_${j} cmap=e2_${j} 'formula=if(A, C, C, B)' outfile=e_${j} --overwrite help=-
done

# Borramos los ficheros temporales creados "e1", "e2" y "tempMedia_tmp"
g.mremove -f rast=${tm}_tmp_*
g.mremove -f rast=e1_* 
g.mremove -f rast=e2_* 

# Ahora vamos a calcular la longitud del día media mensual. Usamos la siguiente referencia:
#Ecological Modeling, volume 80 (1995) pp. 87-95, "A Model Comparison for Daylength as a Function of Latitude and Day of the Year."

# Iniciamos obteniendo un mapa de latitud
r.mapcalculator amap=${tm}_1 'formula=y()' outfile=Latitud --overwrite help=-

# Obtenemos el parámetro "P", que depende del día del año, para cada latitud en el área de estudio.
declare -a P
for j in $(seq 1 365)
do
    tmp1=$(echo "scale=12; (0.0086*(${j} - 186))" | bc -l)
    tmp2=$(echo "scale=12; 0.9671396*(s(${tmp1})/c(${tmp1}))" | bc -l)
    tmp3=$(echo "scale=12; 0.2163108+(2*a(${tmp2}))" | bc -l)
    tmp4=$(echo "scale=12; 0.39795*c(${tmp3})" | bc -l)
    tmp5=$(echo "scale=12; a((${tmp4})/(sqrt(1 - (${tmp4}^2))))" | bc -l)

    i=$((j-1))
    P[$i]=echo "${tmp5}"
done

# Calculamos la longitud del día en función del día del año y de la latitud
for j in $(seq 1 365)
do
    i=${P[$((j-1))]}
    h=$(echo "scale=8; ${i}*180/3.1415925684" | bc)
    r.mapcalc "lengthday_${j}" = "24 - ( (24/3.1415925684) * (3.1415925684/180) *acos( ( sin(0.8333) + ( sin(Latitud) * sin(${h}) ) ) / ( cos(Latitud) * cos(${h}) ) ) )"
done

# Calculamos la longitud media del día para cada mes del año
r=echo lengthday_{1..31}
r=${r// /,}
r.series input=${r} output=D_1 method=average --overwrite 
r=echo lengthday_{32..59}
r=${r// /,}
r.series input=${r} output=D_2 method=average --overwrite 
r=echo lengthday_{60..90}
r=${r// /,}
r.series input=${r} output=D_3 method=average --overwrite 
r=echo lengthday_{91..120}
r=${r// /,}
r.series input=${r} output=D_4 method=average --overwrite 
r=echo lengthday_{121..151}
r=${r// /,}
r.series input=${r} output=D_5 method=average --overwrite 
r=echo lengthday_{152..181}
r=${r// /,}
r.series input=${r} output=D_6 method=average --overwrite 
r=echo lengthday_{182..212}
r=${r// /,}
r.series input=${r} output=D_7 method=average --overwrite 
r=echo lengthday_{213..243}
r=${r// /,}
r.series input=${r} output=D_8 method=average --overwrite 
r=echo lengthday_{244..273}
r=${r// /,}
r.series input=${r} output=D_9 method=average --overwrite 
r=echo lengthday_{274..304}
r=${r// /,}
r.series input=${r} output=D_10 method=average --overwrite 
r=echo lengthday_{305..334}
r=${r// /,}
r.series input=${r} output=D_11 method=average --overwrite 
r=echo lengthday_{335..365}
r=${r// /,}
r.series input=${r} output=D_12 method=average --overwrite 

# Borramos los datos mensuales para liberar espacio en el disco duro
g.mremove -f rast=lengthday_* 

# Calculamos el parámetro L en función de la duración del mes (número de días) y de la longitud media de los días (número de horas de luz)
r.mapcalc "L_1" = "(31/30)*(D_1/12)"
r.mapcalc "L_2" = "(28/30)*(D_2/12)"
r.mapcalc "L_3" = "(31/30)*(D_3/12)"
r.mapcalc "L_4" = "(30/30)*(D_4/12)"
r.mapcalc "L_5" = "(31/30)*(D_5/12)"
r.mapcalc "L_6" = "(30/30)*(D_6/12)"
r.mapcalc "L_7" = "(31/30)*(D_7/12)"
r.mapcalc "L_8" = "(31/30)*(D_8/12)"
r.mapcalc "L_9" = "(30/30)*(D_9/12)"
r.mapcalc "L_10" = "(31/30)*(D_10/12)"
r.mapcalc "L_11" = "(30/30)*(D_11/12)"
r.mapcalc "L_12" = "(31/30)*(D_12/12)"

# Borramos los datos de duración del día media para liberar espacio
g.mremove -f rast=D_*

# Calculamos la ETP mensual
for j in $(seq 1 12)
do
    r.mapcalc "ETP_${j}" = "e_${j} * L_${j}"
done

#Borramos los datos de "e" y "L" mensuales
g.mremove -f rast=e_*
g.mremove -f rast=L_*

# Calculamos la ETP media anual
r.series input=g.mlist pattern=ETP_* sep=, output=ETP method=sum --overwrite

# Borramos los datos de ETP mensuales
g.mremove -f rast=ETP_*

# Calculamos el índice de aridez
r.mapcalc "AridityIndex" = "(${Panual} / ETP)"

# Exportamos los ficheros en formato ascii
r.out.arc input=AridityIndex output=AridityIndex.asc dp=4
r.out.arc input=ETP output=ETP.asc dp=4</pre>]]></content><author><name>dnietolugilde</name></author><category term="Aridez" /><category term="Bash" /><category term="ETP" /><category term="GRASS" /><category term="Script" /><category term="Scripts" /><summary type="html"><![CDATA[Llevo unos días preparando en GRASS una nueva variable bioclimática. Se trata de un índice de aridez, calculado en base a las precipitaciones y a la ETP (Thornwaite). En este script, hay un paso que me ha resultado interesante y es una ecuación para estimar la longitud del día en función del día del año y de la latitud. Dejo aquí el script completo por si a alguien le interesa. También dejo un fichero de clasificación que hace falta para un paso intermedio del script.]]></summary></entry></feed>